Why Claude Code Uses So Many Tokens (and How to See Where They Go)
Every request carries your whole conversation, so context size — not message count — sets what a turn costs. How to see your Claude Code token usage with /usage and /context, why it climbs while you're idle, and what thinking, plan mode and /compact really cost.
 Tahir NazirUpdated October 8, 202617 min read
If Claude Code is using so many tokens that you hit your limit before lunch, the cause is almost never the number of messages you send. Every request carries your entire conversation, so the cost of a turn is set by how much history sits behind it, not by how much you typed. A one-line question in a session you opened this morning still draws usage for the whole morning.
That single fact explains most surprise token usage in a long session. The rest comes from things that spend tokens while you aren't touching the keyboard at all — and from settings, like thinking effort, that multiply the cost of every turn.
The quick version — check usage, then cut it:
- Run
/usage(or its alias/cost) to see this session's tokens by model, and how much came from cache. - Run
/contextto see what's filling the window right now. /clearwhen you switch to unrelated work — it's free./compactisn't.- Lower
/effortfor routine work — thinking is billed as output tokens. - Keep CLAUDE.md under 200 lines, and push noisy output into hooks or subagents.
- Don't leave a large session, scheduled tasks or agent teammates idling past the cache lifetime.
The sections below explain each one.
Two ceilings are in play, and they're shared across Claude Code, Claude chat and Cowork rather than being per-tool: a rolling five-hour window for short-term activity, and a weekly window. Because they're shared, switching models with /model doesn't restore access when you hit a usage limit — though it will keep you working past a model-specific "You've hit your Opus limit" message. If you're not sure whether you've hit a limit or a capacity error, session limits vs 529 overloaded separates the two. If you've already run out, Claude limit resets covers the free reset and when the weekly limit refills. If you're hitting the usage limit too fast, the mechanisms below are where to look before you start rationing your prompts.
The short answer: every turn resends everything
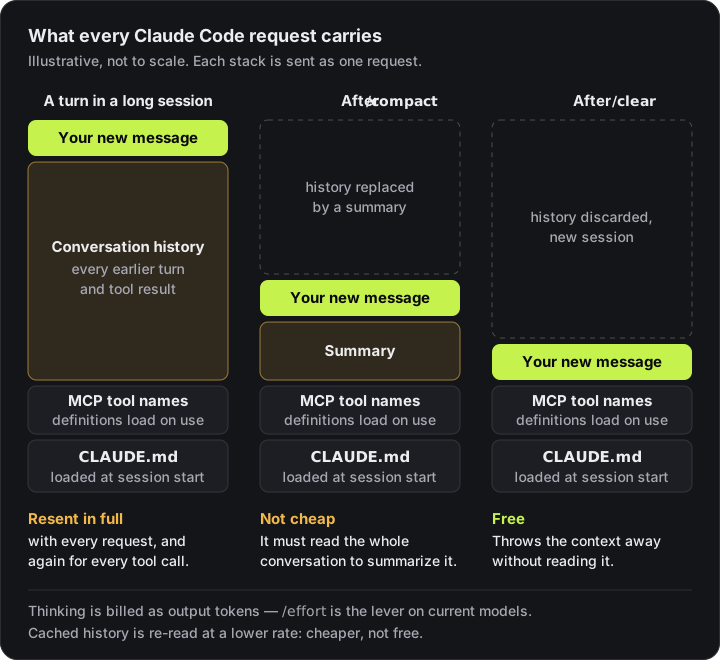
Claude Code sends the full conversation with each request, and each time Claude uses a tool it sends another request carrying that batch of tool results. A task that takes twelve tool calls is twelve requests, each one hauling everything before it.
Prompt caching makes this survivable — repeated content is re-read at the cached token rate rather than full price. But cached is not free, and it means the meaningful number is context size, not message count. To see what a context of your size costs per turn, count it with a token counter, then compare cached and uncached prices in a prompt caching calculator.
How to see your Claude Code token usage
Before changing anything, measure. Three built-in views cover it.
/usage — the per-session breakdown. /cost and /stats are aliases for the same screen. Its Session block lists the session's tokens per model, split into input, output, cache read and cache write, with an estimated dollar figure computed locally at list price. On a subscription that dollar figure isn't what you're billed — the token split is the useful part. Since v2.1.211 these totals reset when /clear starts a new session; earlier versions kept accumulating them for the life of the process.
From v2.1.251 the Session block also has a Prompt cache (main) line: how many requests ran, what share of input tokens came from cache, how many misses there were and how many tokens they re-cached, and whether the cache is warm right now. If you're wondering how much of your usage is uncached, that line answers it directly.
/usage on a plan — what counts against your limits. On a Pro, Max, Team or Enterprise plan, the same screen adds a breakdown:
- Attribution of recent usage to skills, subagents, plugins and individual MCP servers, as percentages.
- Behavior flags when any one behaviour — long context, cache misses — accounts for 10% or more of recent usage.
- Loops: the heaviest
/loopand scheduled tasks, with how often each fires and its per-run tokens (v2.1.242 or later).
Press d or w to switch between the last 24 hours and the last 7 days. These figures come from session history on this machine, so usage from other devices or claude.ai isn't included. The behavior flag is the fastest way to find out which of the causes below is yours, rather than guessing.
/context — what's in the window right now. It draws current context usage as a coloured grid and suggests optimizations for context-heavy tools, memory bloat and capacity. /context all expands the per-item breakdown.
The status line — usage without asking. A custom status line receives context_window.used_percentage, the session's estimated cost.total_cost_usd, and, for claude.ai Pro and Max subscribers, rate_limits.five_hour.used_percentage and rate_limits.seven_day.used_percentage. Showing those permanently is the cheapest way to notice a session getting heavy before it hits a limit.
/usage     # session tokens by model, cache stats, plan usage breakdown
/context   # what is consuming context space right now
For organization-wide or historical numbers, the local commands aren't the tool: API organizations use the Claude Console usage page, Team and Enterprise admins the spend report in org analytics, and any setup can export per-user token metrics through OpenTelemetry.
The cache expires quietly, and the window shrinks
This is the one that catches people, because nothing announces it.
Your first message after a break longer than the cache lifetime misses the cache and reprocesses your entire context at full rate. The lifetime is:
| Situation | Cache lifetime |
|---|---|
| Subscription plan | 1 hour |
| Subscription, drawing on usage credits | 5 minutes |
| API key or cloud provider | 5 minutes by default |
So the moment you exceed your plan allowance and start drawing on usage credits, your effective cache window silently collapses from an hour to five minutes — precisely when you least want expensive turns. You can keep the one-hour lifetime while on credits by setting an environment variable:
ENABLE_PROMPT_CACHING_1H=1Since v2.1.242 you can also choose the main conversation's TTL directly with the promptCacheTtl setting or CLAUDE_CODE_PROMPT_CACHE_TTL (5m or 1h) — on an API key or cloud provider, setting it to 1h is how you get a one-hour cache at all.
If you routinely step away for twenty minutes and come back to a large session, you are paying full price for that context every single time. On Pro and Max, Claude Code now offers to resume a large session from a summary after a long break, so later requests don't carry the full history. And if you came back to find your session already summarized without asking, that's a newer behaviour: Claude Code now compacts idle sessions before the cache expires, and that post covers how to turn it off.
Why token usage climbs while you're not using it
A session sitting open is not a session sitting still. These mechanisms send your full context without you doing anything:
- Scheduled tasks fire on their interval whether or not you're active, and each firing sends the whole context.
- Cross-session messages from another of your sessions are delivered as a new turn while this one is idle — again carrying full context. Set
crossSessionInboundtoholdin settings if you'd rather they queue. - Goal check-ins: while background work keeps an active goal waiting, Claude Code asks Claude to check on it even when the session is idle — a new turn with your full context. Since v2.1.246 that's capped at three idle check-ins per goal between your prompts;
CLAUDE_CODE_GOAL_CHECKIN_MINUTES=0turns them off. - Agent teammates keep consuming tokens until they exit or the session ends. They do not idle politely.
- Background summarization runs so
claude --resumeworks. This one is genuinely small — typically under $0.04 per session.
The first four are worth auditing if your usage climbs overnight. The last is noise.
Agent teams are the expensive one
Each teammate runs its own Claude instance with its own context window, so cost scales with team size rather than with the work. The docs put it precisely: agent teams use approximately 7x more tokens than standard sessions when teammates run in plan mode.
Teammates also load CLAUDE.md, MCP servers and skills automatically, so each one starts with a full context before doing anything. If you spawn a team, keep it small, use Sonnet for teammates, and shut them down when their work is done rather than leaving them parked.
Thinking tokens: MAX_THINKING_TOKENS vs effort levels
Extended thinking is billed as output tokens, and the default budget can run to tens of thousands of tokens per request depending on the model. You're charged for all thinking generated, even when it's collapsed or redacted in the UI.
How you control it depends on the model:
| Model | Control that works |
|---|---|
| Adaptive reasoning: the Fable models, Sonnet 5 and later, Haiku 5.5, Opus 4.7 and later | /effort — a nonzero MAX_THINKING_TOKENS is ignored |
| Fixed thinking budget | MAX_THINKING_TOKENS, e.g. MAX_THINKING_TOKENS=8000 |
| Opus 4.6 and Sonnet 4.6 | Adaptive by default; CLAUDE_CODE_DISABLE_ADAPTIVE_THINKING=1 reverts to the fixed budget MAX_THINKING_TOKENS controls |
So if you set MAX_THINKING_TOKENS on a current model and saw no difference, that's why. Effort is the lever now. It runs from low through medium, high, xhigh and max (the exact levels vary by model), and each step trades token spend against capability. The default is medium on Opus 5.5, Sonnet 5.5 and Haiku 5.5, xhigh on Opus 4.7, and high on the other models that support effort. Anthropic's own guidance on max: it can show diminishing returns and is prone to overthinking, so test before adopting it broadly.
Three details that matter for cost:
ultrathinkin a prompt asks for deeper reasoning on that one turn without changing your session's effort level.- Changing effort mid-session can cost you the cache. On most models, the next request re-reads the whole conversation with no cache hits, and Claude Code asks you to confirm while the cache is warm. On Opus 5.5, Sonnet 5.5, Haiku 5.5 and Fable 5.1 with an API key or a Claude subscription, the cache survives the change.
- You can't turn thinking off on Opus 5.5, Sonnet 5.5, Haiku 5.5 or the Fable models —
MAX_THINKING_TOKENS=0and the/configtoggle have no effect there. Effort is the only control.
Does plan mode use more tokens?
Switching into plan mode doesn't cost you the cache. Plan mode appends its instructions as conversation messages, so the cached prefix stays intact — mode changes are cache-safe. What plan mode spends is the reading and planning it does, counted like any other turn.
Two setups are different:
opusplanuses Opus while you're in plan mode and Sonnet for execution. Each plan-mode toggle is a model switch, and a model switch starts a fresh cache.- Agent teams in plan mode are where the ~7x figure above comes from.
Anthropic's cost guide actually recommends plan mode for complex tasks: Claude explores and proposes an approach for your approval, which prevents expensive rework when the first direction is wrong.
/compact is expensive. /clear is free.
This surprises people who reach for /compact as the cheap option.
/compact has to read the conversation it summarizes, so compacting a large context is itself a large request. /clear throws the context away without reading it and costs nothing.
The right rule is about intent, not price:
- Switching to unrelated work?
/clear. Carrying stale context into a new task taxes every subsequent message for no benefit. - Need continuity?
/compact, and tell it what matters:
/compact Focus on the migration plan and the failing test outputYou can also make that persistent by putting compaction instructions in your project's CLAUDE.md:
# Compact instructions

When you are using compact, please focus on test output and code changes
One practical habit: /rename your session before clearing, so /resume can find it later. You get the fresh context without losing the thread.
If compaction keeps firing and the context fills straight back up, that's a different problem — autocompact is thrashing because something keeps dumping a huge payload into context, and the fix is to find that payload rather than compact harder.
What's actually sitting in your context
Run /context before optimizing anything — the answer is often not what you'd guess.
CLAUDE.md loads at session start and stays there. If it carries detailed instructions for PR reviews or database migrations, those tokens are present while you're doing something completely unrelated. The guidance is to keep it under 200 lines and move workflow-specific instructions into skills, which load only when invoked.
MCP servers are less of a problem than they used to be. Tool definitions are now deferred by default, so only tool names enter context until Claude actually uses one. Still worth running /mcp and disabling servers you aren't using — and where a CLI exists (gh, aws, gcloud, sentry-cli), it's more context-efficient than an MCP server because it adds no per-tool listing at all. If you're wrestling with MCP servers generally, I wrote up why they fail to show up in Claude Code.
Push volume out of your main context
The highest-leverage change isn't spending less, it's keeping bulk output out of the conversation entirely.
Hooks can preprocess before Claude ever sees the data. Instead of Claude reading a 10,000-line log to find the errors, a hook greps for them and returns only the matches — tens of thousands of tokens down to hundreds. This PreToolUse hook rewrites test commands to surface only failures:
{
  "hooks": {
    "PreToolUse": [
      {
        "matcher": "Bash",
        "hooks": [
          { "type": "command", "command": "~/.claude/hooks/filter-test-output.sh" }
        ]
      }
    ]
  }
}
Subagents isolate verbose operations. Run tests, fetch docs or process logs in a subagent and the noisy output stays in its context — only the summary comes back to your main conversation. The subagent's own requests still draw on your usage, so give simple subagent tasks a smaller model.
What normal actually looks like
Worth calibrating against, before you conclude something is broken. Across enterprise deployments the average is around $13 per developer per active day, and $150–250 per developer per month, with 90% of users staying below $30 per active day.
If you're well outside that, the docs point at two habits rather than exotic causes: long sessions that were never cleared, and Opus left as the default model when Sonnet would do. Sonnet handles most coding work well and costs less; reserve Opus for genuine architectural decisions and multi-step reasoning, and use model: haiku for simple subagent tasks.
Before you go hunting for exotic explanations, run /insights. It analyses your recent sessions on this machine and writes an HTML report on how you actually work — what you spend time on, where requests get misunderstood, where turns get wasted. That's usually a faster route to reducing Claude Code token usage than tuning any single setting.
Key takeaways
- Cost is driven by context size, not message count — every request carries the whole conversation, plus one more request per tool call.
- /usage (alias /cost, /stats) shows session tokens by model with cache reads and writes; /context shows what is in the window; the status line can show both continuously.
- The prompt cache lifetime silently drops from 1 hour to 5 minutes once you start drawing on usage credits. ENABLE_PROMPT_CACHING_1H=1 or promptCacheTtl restores it.
- Adaptive-reasoning models ignore a nonzero MAX_THINKING_TOKENS — use /effort, and expect a cache miss when you change it mid-session on most models.
- /clear is free; /compact has to read the conversation it summarizes, so it is itself an expensive request.
- Scheduled tasks, cross-session messages, goal check-ins and idle agent teammates all resend your full context while you are doing nothing.
Frequently asked questions
Why does a one-line question cost so much in a long session?
Claude Code sends your full conversation with every request. A short question in a session that has been open all day still draws usage for the entire history behind it. Prompt caching makes those tokens cheaper, not free — they are re-read at the cached rate on every turn.
How do I see how many tokens my Claude Code session used?
Run /usage — /cost and /stats are aliases. Its Session block lists input, output, cache-read and cache-write tokens per model for the current session, and the totals reset when /clear starts a new one. Run /context to see what is taking up the context window right now, or configure your status line to show context usage continuously. On a Pro, Max, Team or Enterprise plan, /usage also attributes recent usage to skills, subagents, plugins and MCP servers over the last 24 hours or 7 days.
Is /compact cheaper than /clear?
No, the opposite. /compact has to read the conversation it summarizes, so compacting a large context is itself a large request. /clear costs nothing. Use /compact when you need continuity and /clear when you are switching to unrelated work.
Why did my usage jump after I came back from lunch?
You missed the prompt cache. The cache lifetime is one hour on a subscription, but it drops to five minutes once you are drawing on usage credits, and it is five minutes by default on an API key or cloud provider. The first message after that window reprocesses your entire context at full price.
Can Claude Code use tokens while I am not typing?
Yes. Scheduled tasks fire on their interval and send your full context each time, cross-session messages are delivered as a new turn while the session is idle and do the same, goal check-ins can start a turn while background work runs, and every active agent teammate keeps consuming tokens until it exits. Background summarization also runs, though that is typically under four cents a session.
Does MAX_THINKING_TOKENS still work?
Only on models with a fixed thinking budget. Adaptive-reasoning models — the Fable models, Sonnet 5 and later, Haiku 5.5, and Opus 4.7 and later — ignore a nonzero MAX_THINKING_TOKENS, so use /effort to control how much they think. On Opus 4.6 and Sonnet 4.6 you can set CLAUDE_CODE_DISABLE_ADAPTIVE_THINKING=1 to go back to the fixed budget that MAX_THINKING_TOKENS controls.
Does plan mode use more tokens in Claude Code?
Switching into plan mode does not cost you the prompt cache: its instructions are appended as conversation messages, so the cached prefix stays intact. Two setups are different. The opusplan model setting switches between Opus and Sonnet as you enter and leave plan mode, so each toggle starts a fresh cache, and agent teams use approximately 7x more tokens than standard sessions when teammates run in plan mode. Anthropic's cost guide recommends plan mode for complex tasks because it prevents expensive rework.
Most "Claude Code is burning tokens" problems come down to a session that has been open too long carrying context nobody needs any more. /usage tells you which behaviour is responsible, /context tells you what's in there, and /clear is the cheapest command you have.
If the problem is an error rather than a bill, every Claude Code error and its fix groups the common ones by cause.
If you're deciding how to structure project configuration in the first place, I compared how Claude Code and Cursor handle it in Claude Code vs Cursor context management — and ContextZero came out of the same problem.
References
- Manage costs effectively — Claude Code docscode.claude.com · accessed 2026-10-08
- Commands reference — Claude Code docscode.claude.com · accessed 2026-10-08
- Model configuration: effort levels and extended thinking — Claude Code docscode.claude.com · accessed 2026-10-08
- Prompt caching — Claude Code docscode.claude.com · accessed 2026-10-08
- Customize your status line — Claude Code docscode.claude.com · accessed 2026-10-08
- Connect Claude Code to tools via MCPcode.claude.com · accessed 2026-08-14
Last reviewed October 8, 2026

Tahir Nazir
Senior AI Engineer & Full-Stack Lead
5+ years shipping AI-powered products — RAG pipelines, agentic workflows, and MCP tooling. Top Rated on Upwork with a 100% job success score.
More about Tahir →Related articles
Claude Limit Reset: The Free Full Reset, /limit-reset and What Each Reset Refills
Anthropic gave every Pro, Max, Ultra and Team account one free full reset to use before 10 December 2026. What each kind of Claude limit reset refills, where the 'Reset for free' button is, why your weekly reset day doesn't move, and why Claude Code can answer 'Unknown command: /limit-reset'.How-toAI Engineering22 min readClaude Code 'Compacted Using a Summary Written While You Were Away'? Turn It Off
You stepped away and came back to 'Compacted using a summary written while you were away', or in the terminal 'Compacted while idle, before the prompt cache expired'. It's idle compaction, a cost-saving feature Anthropic switched on server-side. How to turn it off in settings.json or /config, and the exact rules I found in the code.TroubleshootingAI Engineering26 min readWhy Is Claude Code So Slow, Hanging or Eating Memory? Start With the Silent Failures
High CPU, frozen commands and missing search results usually trace to a handful of specific causes — a compaction loop, a bundled ripgrep that won't run, or WSL quietly returning fewer matches while claude doctor reports everything as OK.TroubleshootingAI Engineering9 min read
Follow along
New posts land here first. Follow along by RSS, or get in touch if you are building something similar.